Personal project10 min read
Hypeoslav - AI Media Holding
Tech stack
Contents
- Challenge
- Discovery
- Competitor Research
- Options Considered
- Decision
- Implementation
- Outcome
- Landing Page and Brand
- Channel Identity
- Pipeline in Blender
- Animated Subtitles
- Multilingual Intros and Viral Covers
- Localised Script Files
- Avatar Generation
- Desktop Visual Editor
- Trend Monitoring
- Raising the YouTube API Quota
Services
- →AI pipeline architecture and development (Python)
- →Telegram Bot interface for pipeline control
- →Multi-service AI integration (image, text, audio)
- →Post assembly and multi-platform publishing automation
- →YouTube monetisation setup and AdSense integration
Deliverables
- ✓Decentralised content generation pipeline triggered from Telegram
- ✓Integrations: Midjourney, DALL·E, Recraft, ChatGPT, Gemini, ElevenLabs
- ✓Production time: from 2, 3 hours and then under 5 minutes per post
- ✓Multiple monetised channels running in parallel with one operator
Challenge
Co-founded Hypeoslav as an AI-native media holding, multiple content channels producing image, text, and audio content at scale. The economics only work if production cost per post is near zero. Manual workflows across Midjourney, ChatGPT, ElevenLabs, and publishing tools were taking 2, 3 hours per post. That wasn't a media business; it was a manual production studio.
Discovery
Breaking down the content production workflow revealed that every step was mechanical: write prompt and then generate image, write caption, generate voiceover, assemble post and then publish to channel. None of these steps required human creative judgment once the brief was defined. The bottleneck wasn't creativity. It was orchestration.
Competitor Research
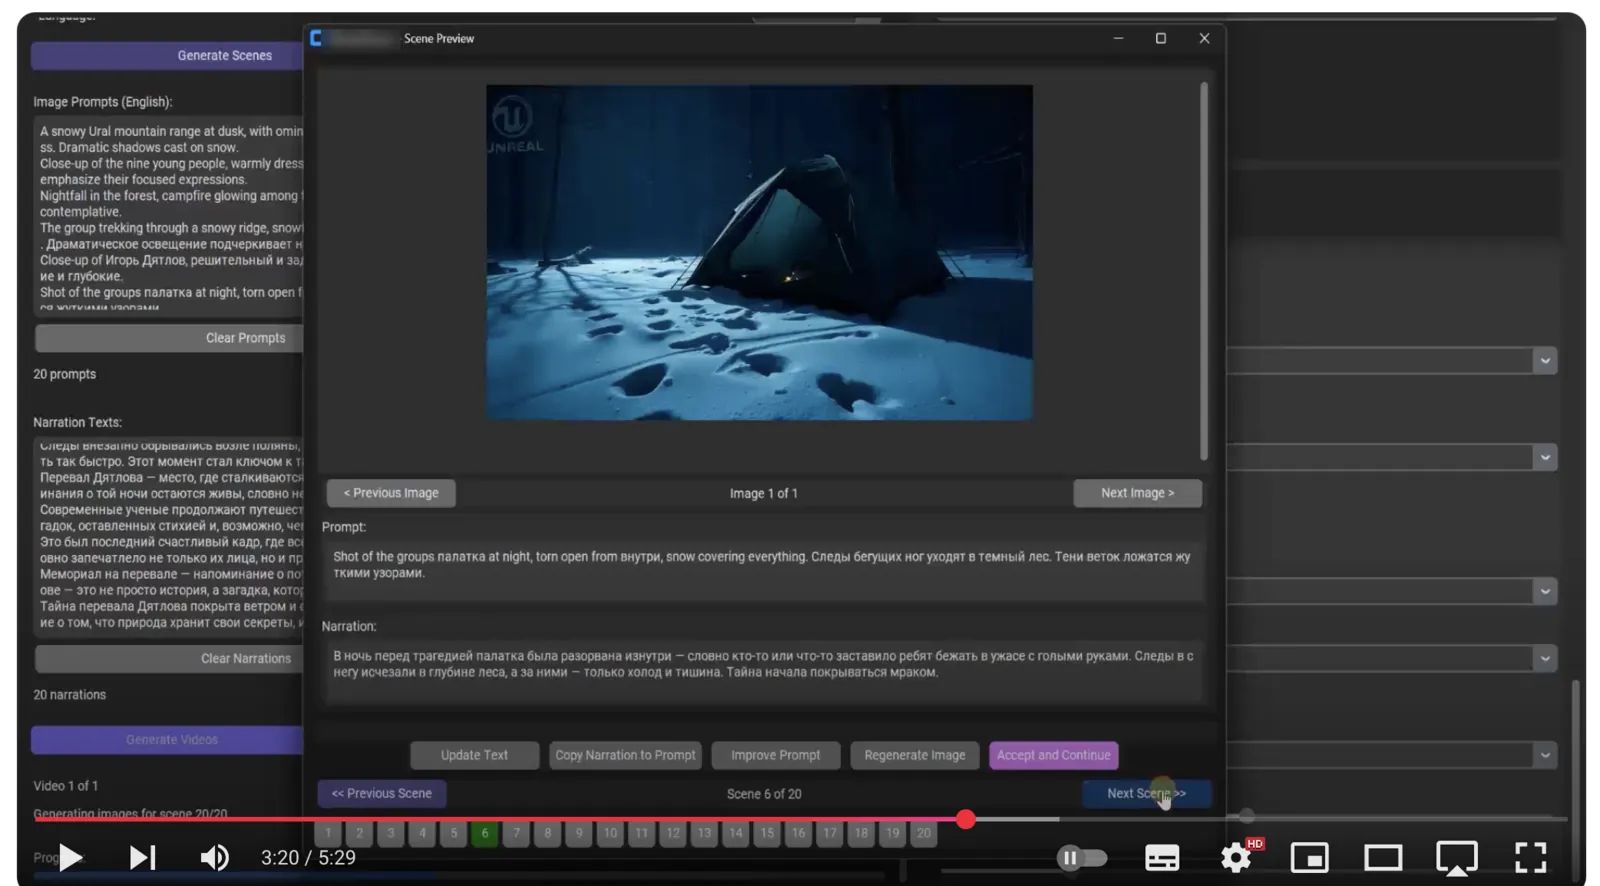
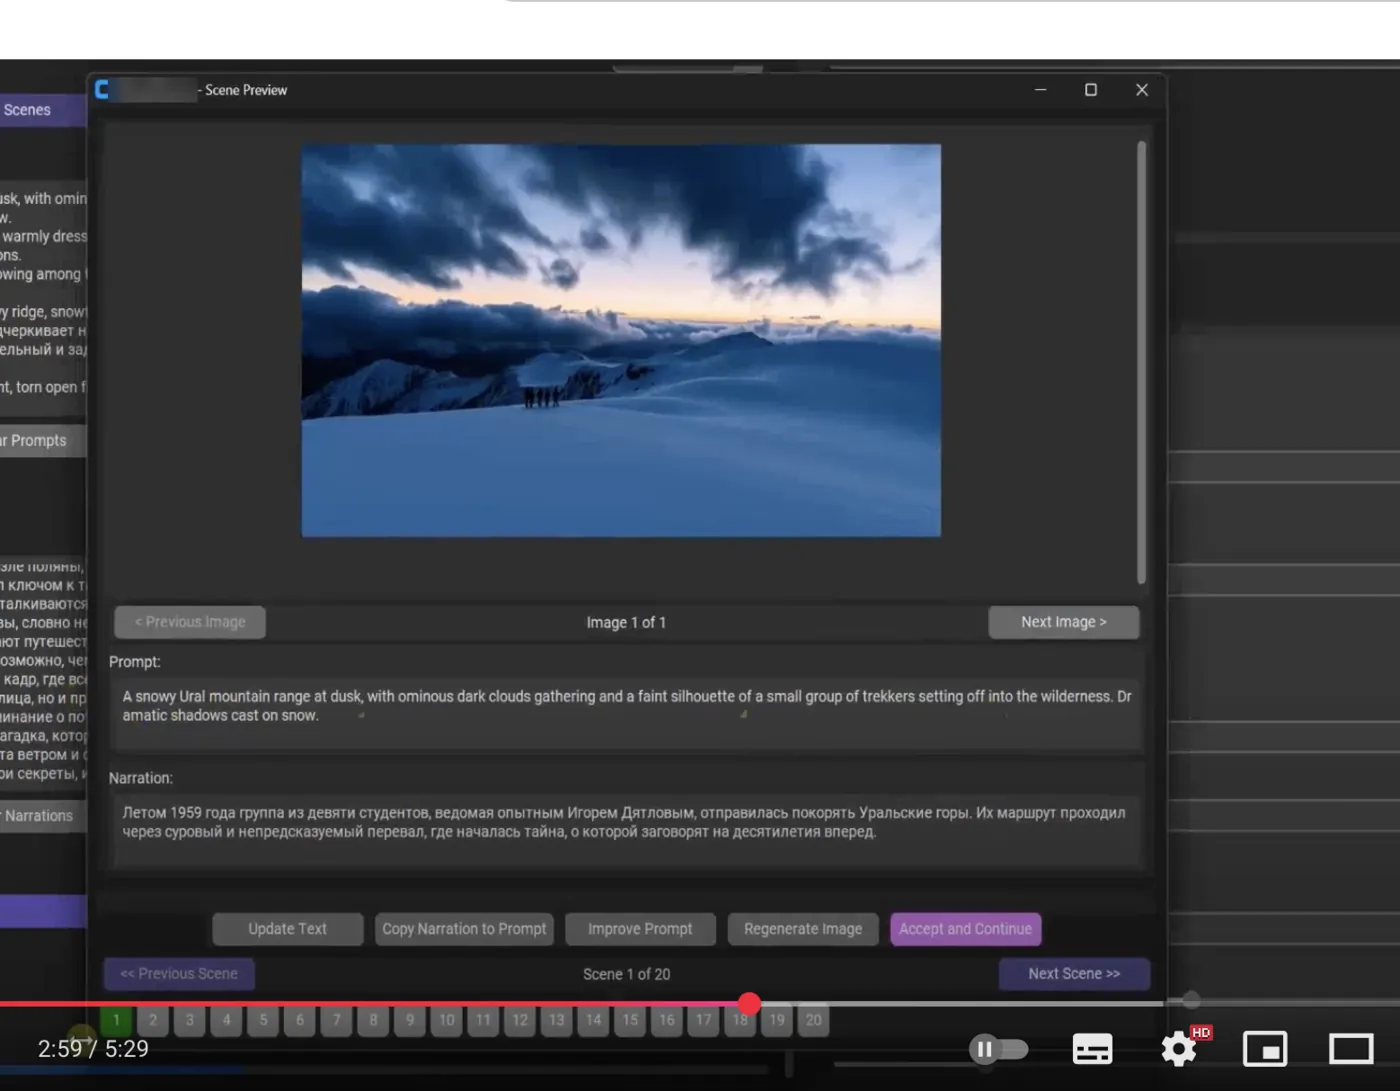
Before building our own pipeline, we studied competing tools and ran test projects through them. We wanted to keep what already worked, fix what we didn't like, and find the places where our pipeline needed its own approach. The screenshots show one of those tools: a desktop app that splits a script into scenes and pairs each scene's image prompt with its narration. The editor can improve a prompt, regenerate an image, or accept the scene and move to the next one. The product name is hidden.
Competitor scene editor, product name hidden
Options Considered
- No-code automation tools (Zapier, Make), evaluated. Couldn't handle the multi-step AI API calls, error handling, or conditional routing between generation services.
- Custom web dashboard: rejected. Editors didn't want another tab to manage; the interface needed to be where they already worked.
- Telegram Bot as the control interface + Python backend pipeline: chosen. Editors already used Telegram; bot commands gave instant access to the pipeline from any device.
Decision
Python orchestration layer connects to all AI APIs. Telegram Bot API is the interface: an editor sends a content brief, the pipeline fans out to the appropriate generation services in parallel, assembles the result, and either auto-publishes or presents a preview for approval. Each channel type (image-heavy, text-heavy, audio) has its own pipeline variant.
Implementation
Integrated Midjourney (via Discord API automation), DALL·E and Recraft for image generation, ChatGPT and Gemini for captions and scripts, and ElevenLabs for voiceover. Each service has its own async handler with retry logic and fallback routing, if Midjourney is slow, the pipeline switches to Recraft automatically.
Post assembly merges the generated assets into platform-native formats for Telegram channels, YouTube Shorts, and Instagram. Scheduling is handled via a queue that distributes posts across optimal publishing windows. YouTube AdSense monetisation was set up across the video channels.
Outcome
Content production time dropped from 2, 3 hours to under 5 minutes per post. Multiple channels run in parallel with one operator. The infrastructure handles the creative pipeline end-to-end. The human role is brief definition and quality gate, not production execution.
Landing Page and Brand
Hypeoslav got a product landing page and an identity of its own. At its centre is a girl in a kokoshnik with YouTube play buttons on her cheeks; the variants below set the name in Cyrillic and in Latin on different backgrounds. Through the site visitors could get in touch, email the team, see who is on it and watch examples of our videos. Later we partnered with other viral video producers: we discussed niches with them and worked together.
Logo variants and the wordmark
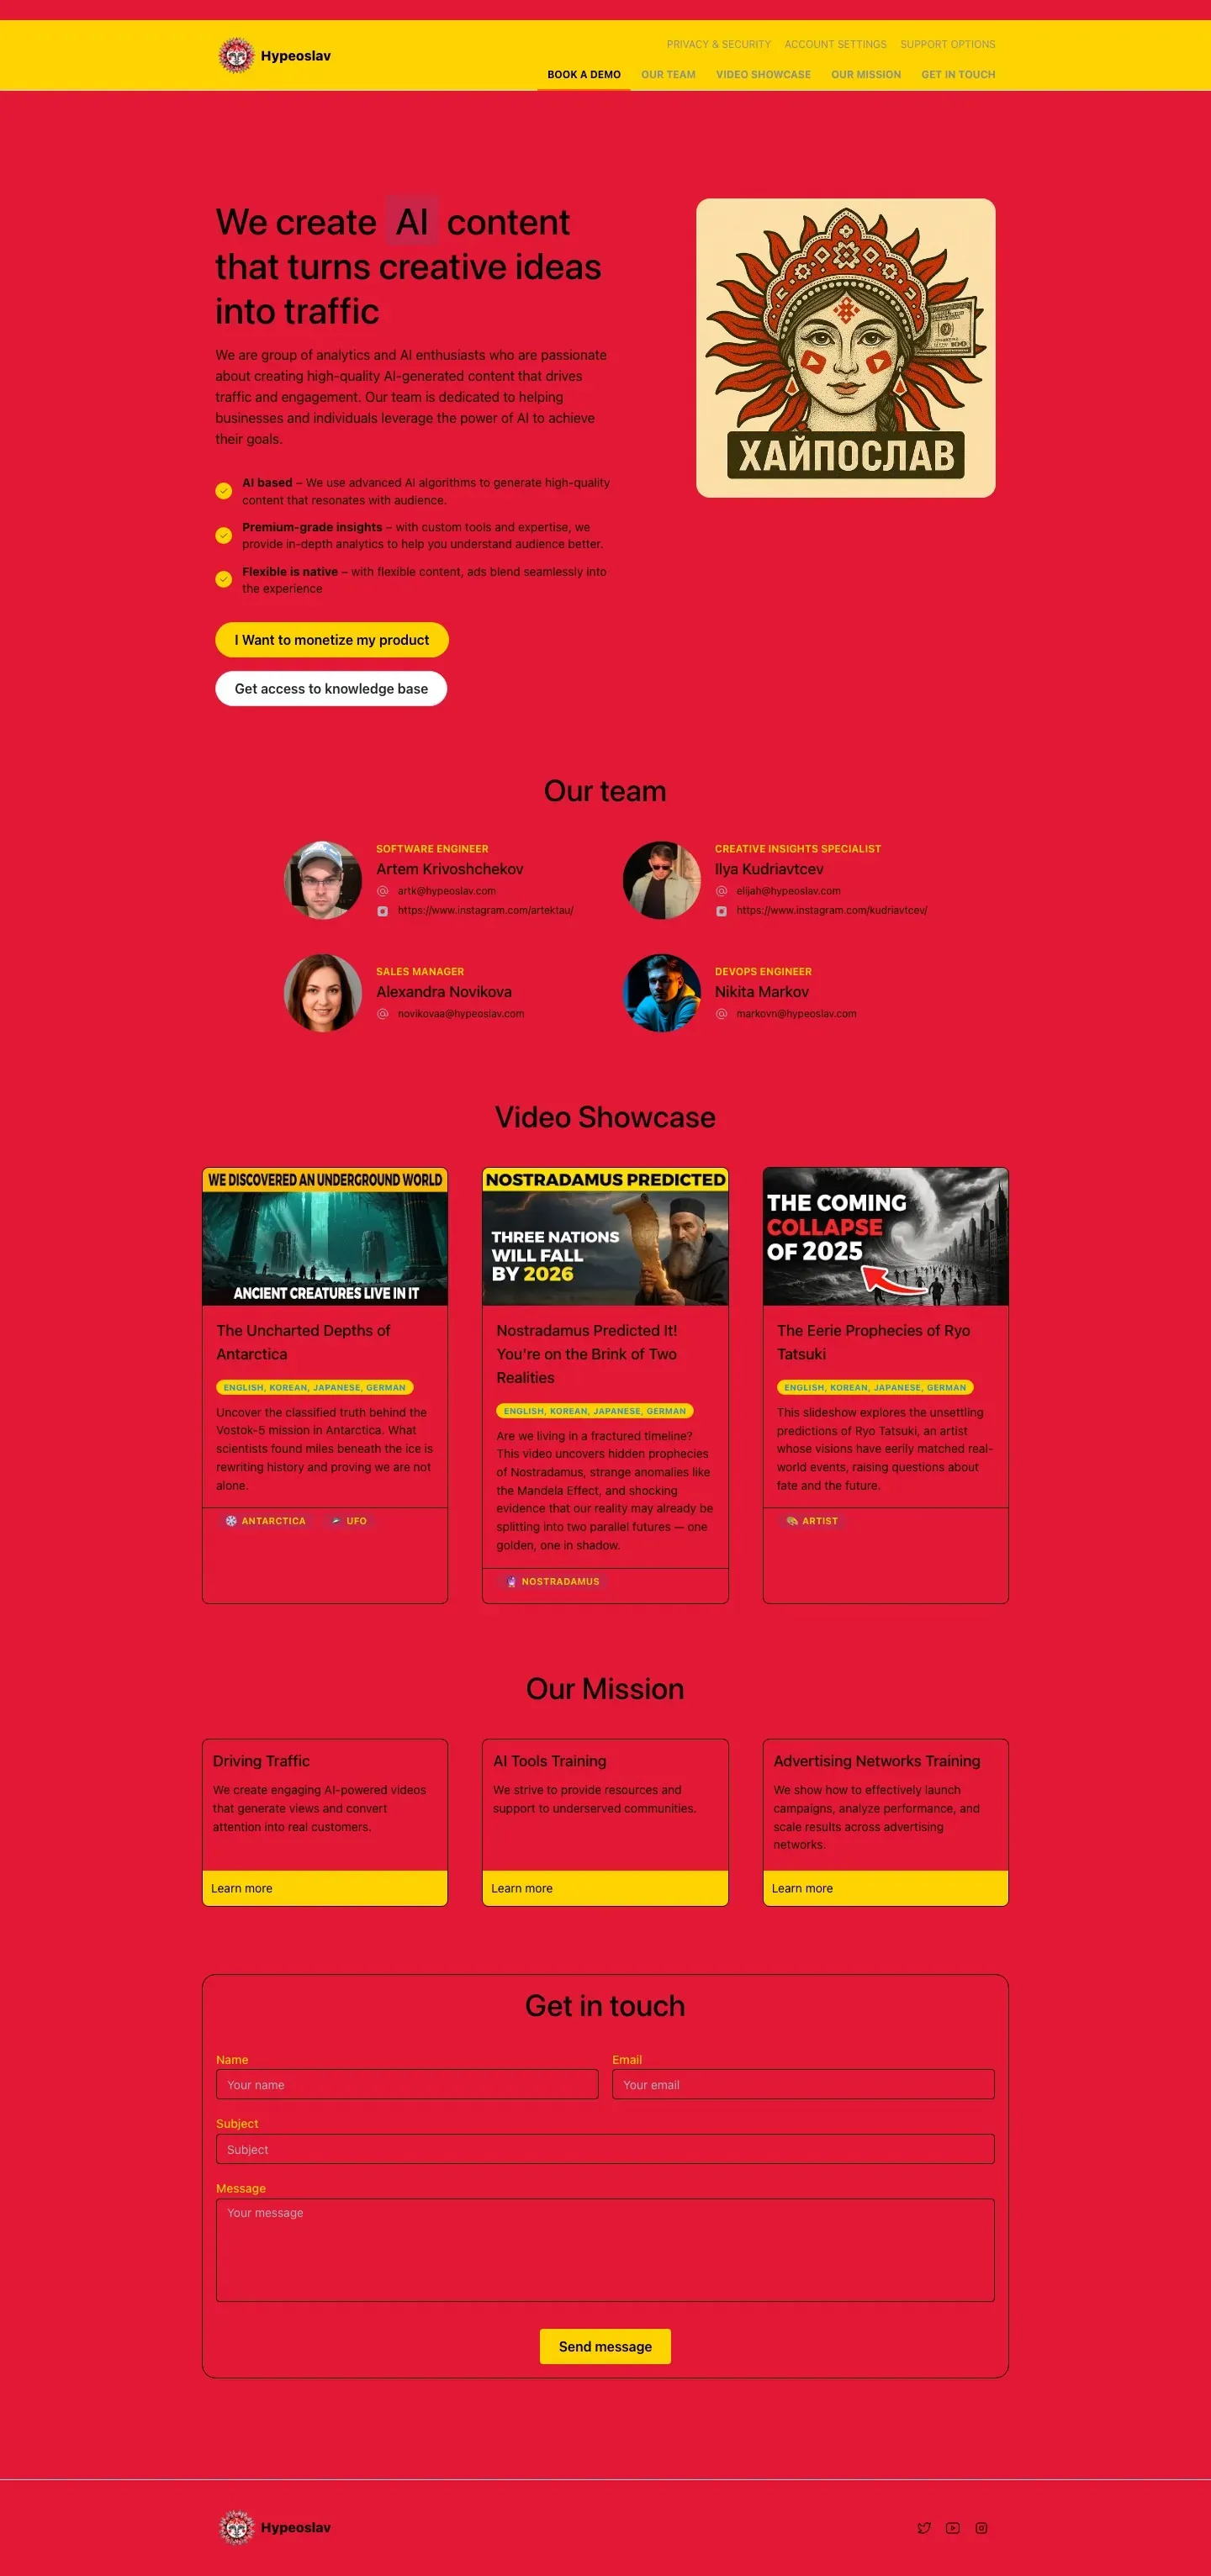
Static snapshot — scrollable Safari preview
Channel Identity
Each themed channel got its own identity: an avatar and a background banner, designed around what makes viral titles and thumbnails work. A single theme ran in several languages at once, so the same brand shows up with Korean, English and German lettering. The names were localised rather than translated word for word: "The Mental Key" in English became "Open the Door of the Cortex" in Korean.
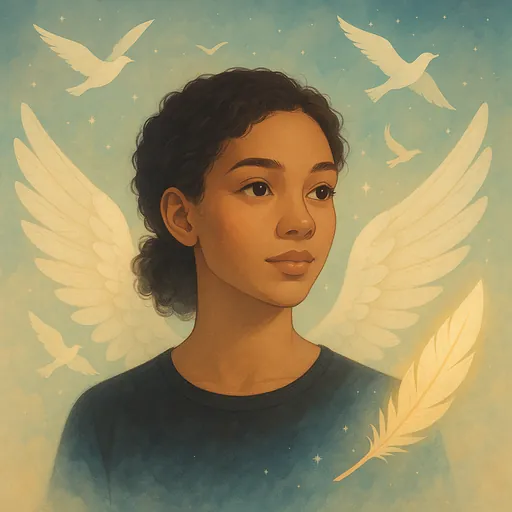
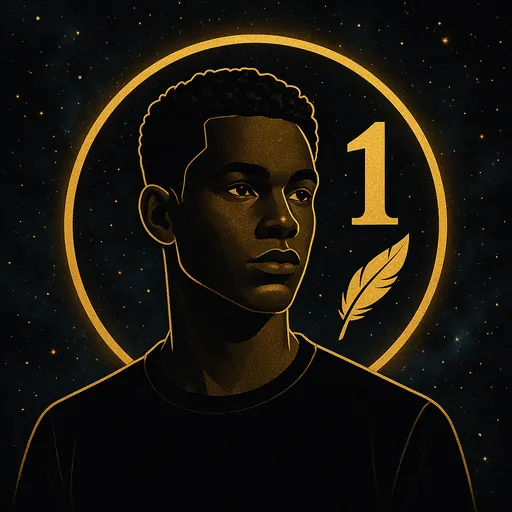
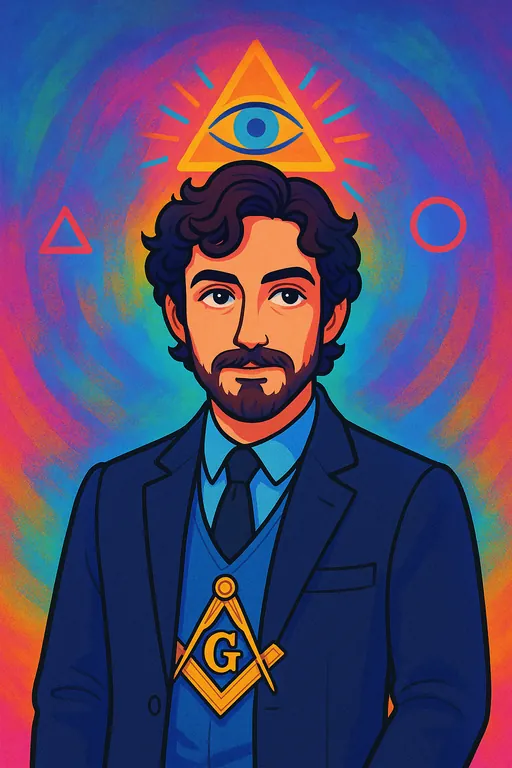
Channel avatars
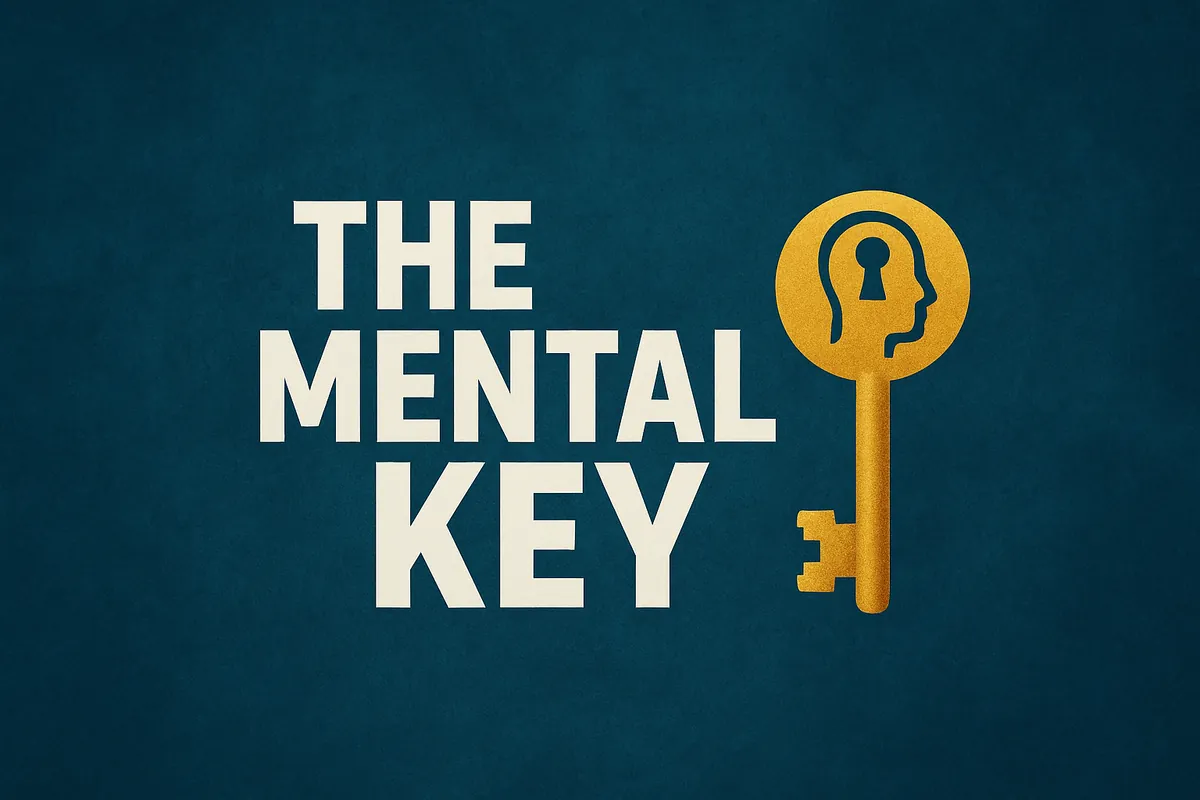
Channel banners
Pipeline in Blender
An intermediate stage of the pipeline, captured in Blender. The scene is assembled automatically: images are placed and aligned, the avatar is composited on top, and a smoke effect runs over the shot (an early version of it). Every image and every scene in the clip came out of the LLM stage. Subtitles were laid on separately, outside Blender.
Blender is driven entirely from Python. The script builds the timeline, spreads clips and overlays across channels, composes the frame and applies effects, for example a Ken Burns zoom with a random focal point on every still image.
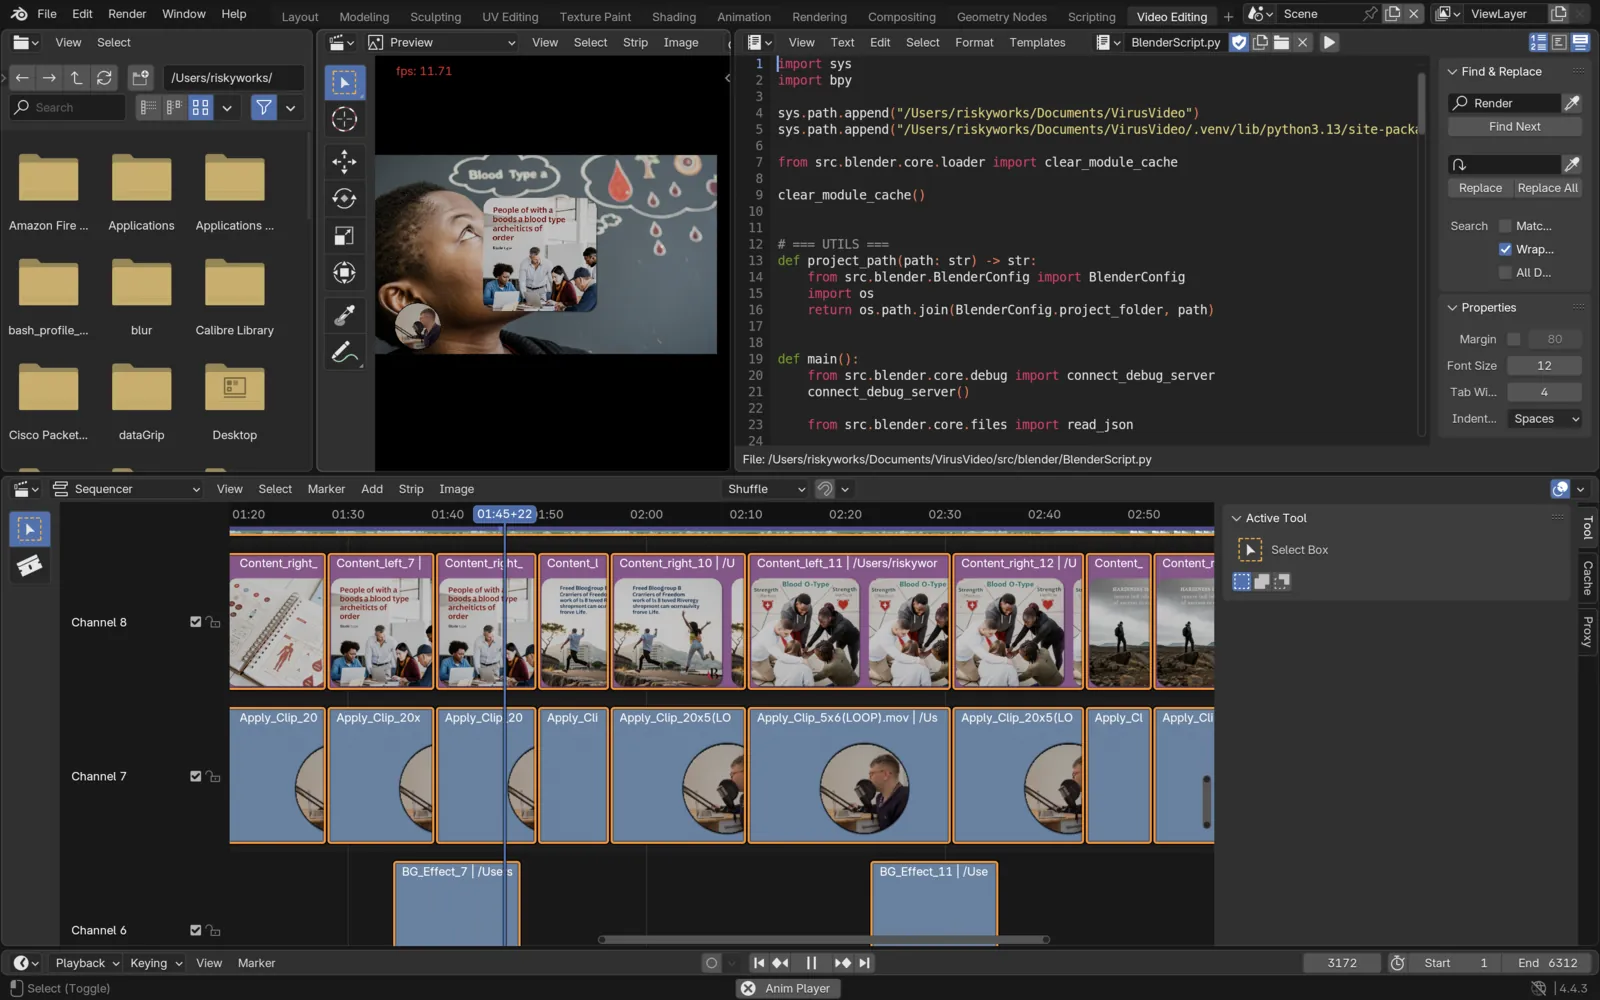
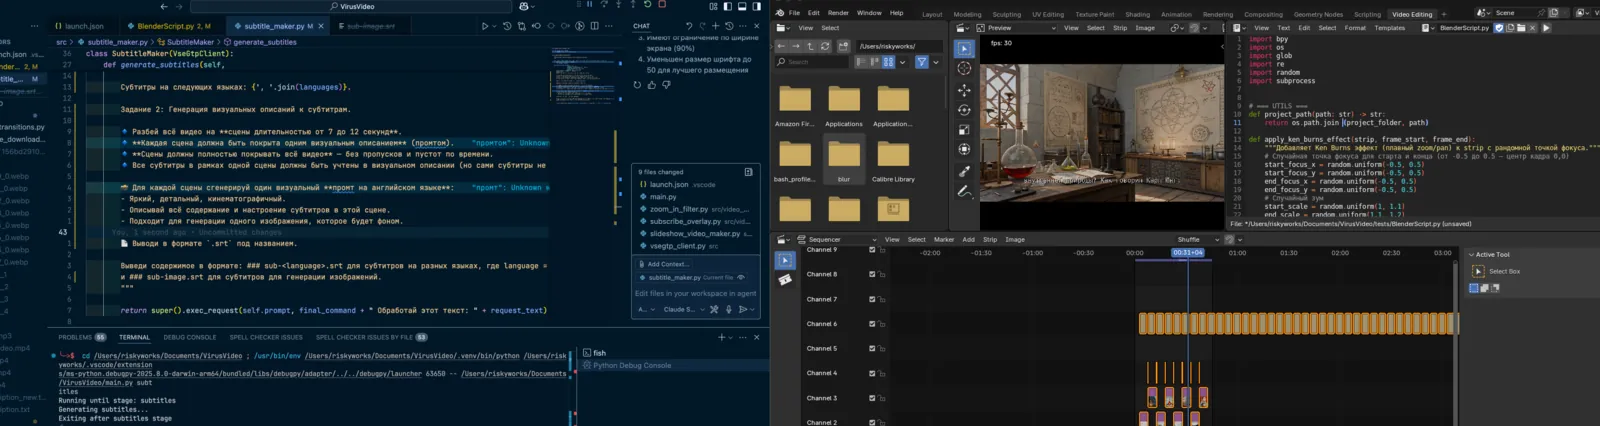
The timeline, composition and effects are assembled by Python code
Animated Subtitles
Subtitles are animated karaoke-style, with the current word highlighted as it is spoken. Blender had no workable subtitle support, so the merge was done in ffmpeg: Blender put out a clean render and the subtitle track was burned on in a separate pass. The styling was reworked later on. A drop shadow was added, and the font was extended with the glyphs it was missing so it could carry other languages, Korean and Japanese included. The original version broke on those.
Subtitles are generated automatically and come in several styles, karaoke among them, where each word lights up as it is spoken.
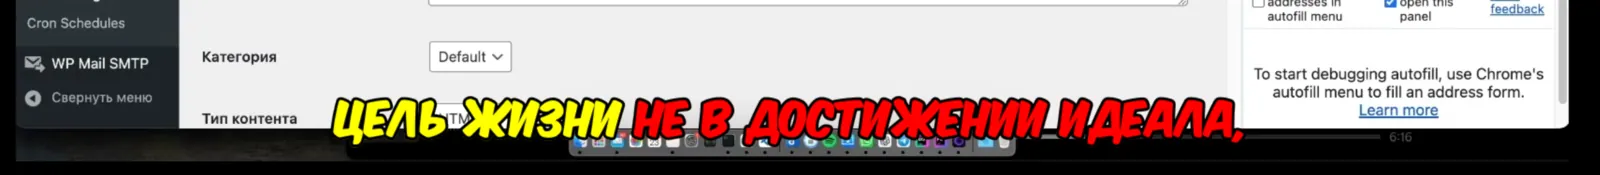
Karaoke subtitle style
Multilingual Intros and Viral Covers
Generated intros in several languages, shown alongside the cover images that front the videos. Voice was the part that took the most searching: a run of local models was tested, Kokoro-based ones and the Facebook releases among them, before ElevenLabs was picked as the main voice tool.
The cover images get their own prompt set. Rather than describing a picture, the prompts encode what already worked, taking apart reference thumbnails that had gone viral and carrying their patterns over into the generated ones.
Localised Script Files
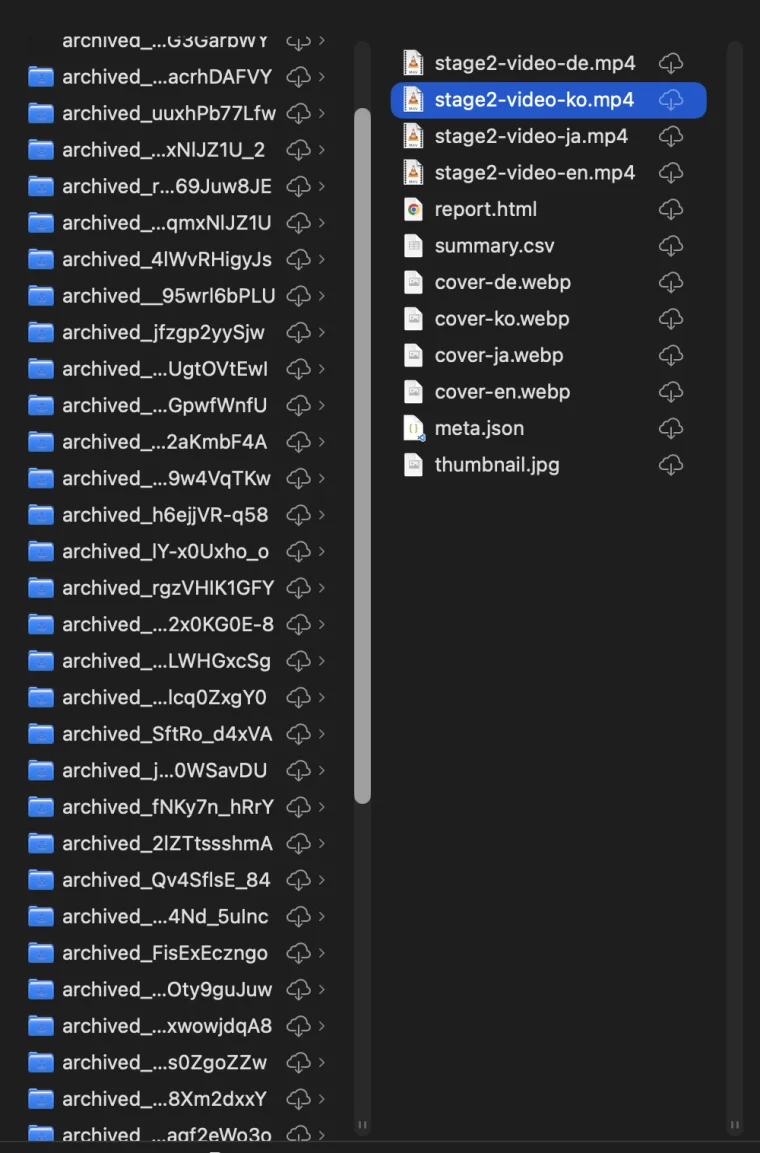
The file structure the pipeline works from: rewritten scripts plus their metadata, one set per language. The constraint that shaped it is that a video has to come out at roughly the same length whatever language it ends up in, so the scripts are adapted to fit a duration rather than translated line by line. A literal translation drifts, some languages run visibly longer than others at the same word count, and the timing against the visuals falls apart.
Avatar Generation
Avatars are generated in ComfyUI across a set of models, and the pipeline pulls video out of it through an integration rather than calling a paid service. That kept the cost down, external generation services were the single largest line item, and it also put generation quality under direct control: the model, the settings and the number of steps are dialled per channel instead of accepting whatever a vendor endpoint returns.
We chose ComfyUI because the results from other interfaces didn't satisfy us, and built our own avatar generation workflow in it. Avatars were supported on purpose: a presenter on screen raises viewer trust and video retention.
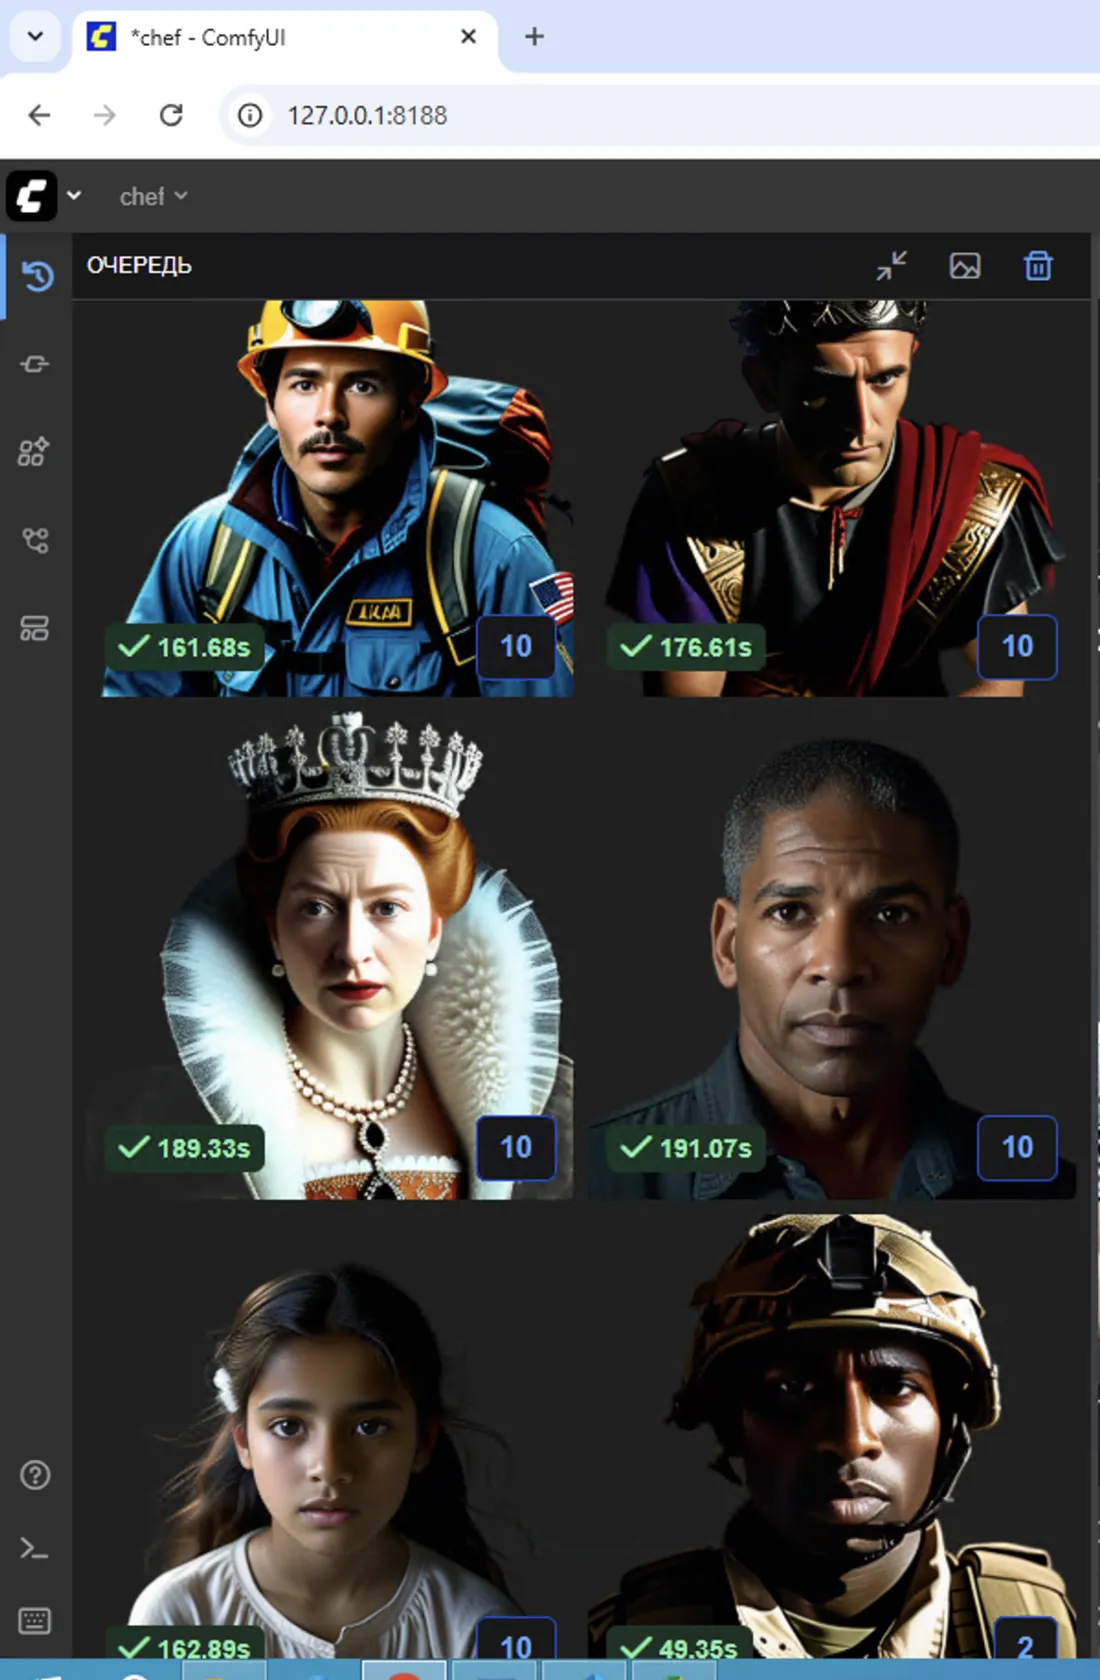
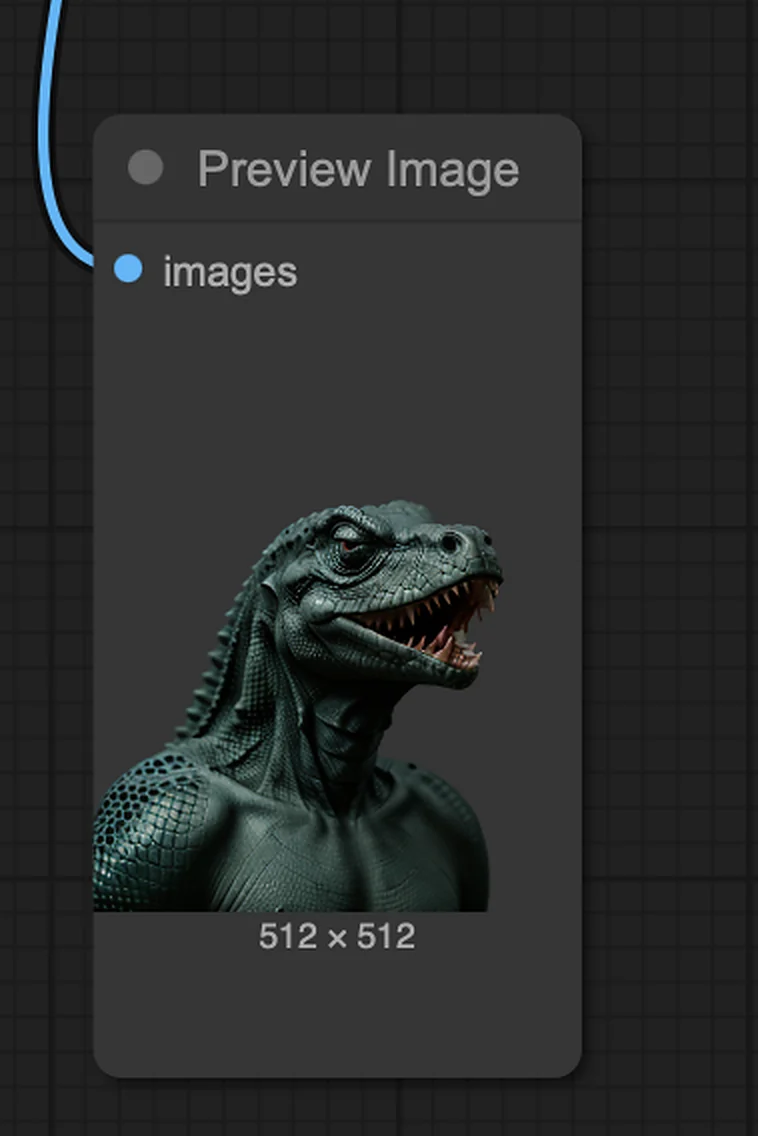
Avatars generated by our ComfyUI workflow
Telegram Control Bot
Running the pipeline 24/7 meant it had to be steerable from a phone, so the control surface is a Telegram bot. Work is multi-threaded: tasks go into a queue and slave workers pick them up as they free up, rather than one job blocking the line behind it.
Video generation runs stage by stage, and the stages that need a human eye stop for one. The bot reports that a stage is done and moves on to other work instead of idling. The operator opens the result from Google Cloud, which is why the check works from a phone, and answers accept or redo, with the option to change the prompt before the retry. The finished video is uploaded to Google Drive.
The bot also carries the failure path: a task that fails is reported with its error instead of dying quietly in the queue, and it can be restarted straight from the chat.
The full step-by-step run, with the intermediate results approved one stage at a time.
How the Bot Is Wired
The bot runs on a custom web service on our own server. It listens for commands, hands the tasks out to the workers and writes the result back into the chat. Every intermediate file that needs a human decision, accept or redo, is uploaded to Google Cloud, so the whole pipeline can be administered remotely, on the go. Image moderation on a PC got a dedicated desktop app, RenderOrc, described below in Desktop Visual Editor.
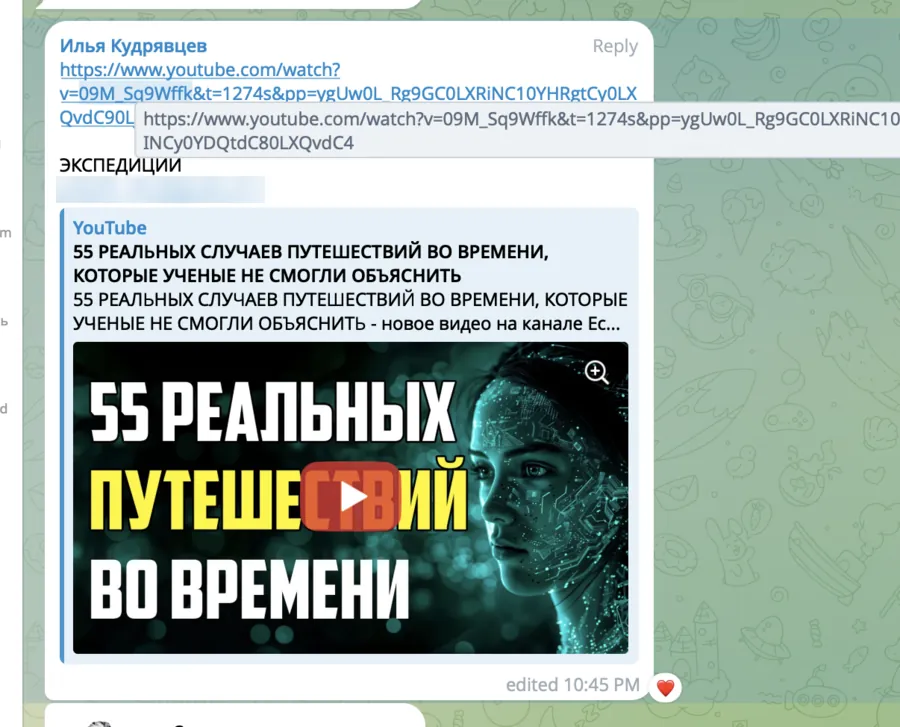
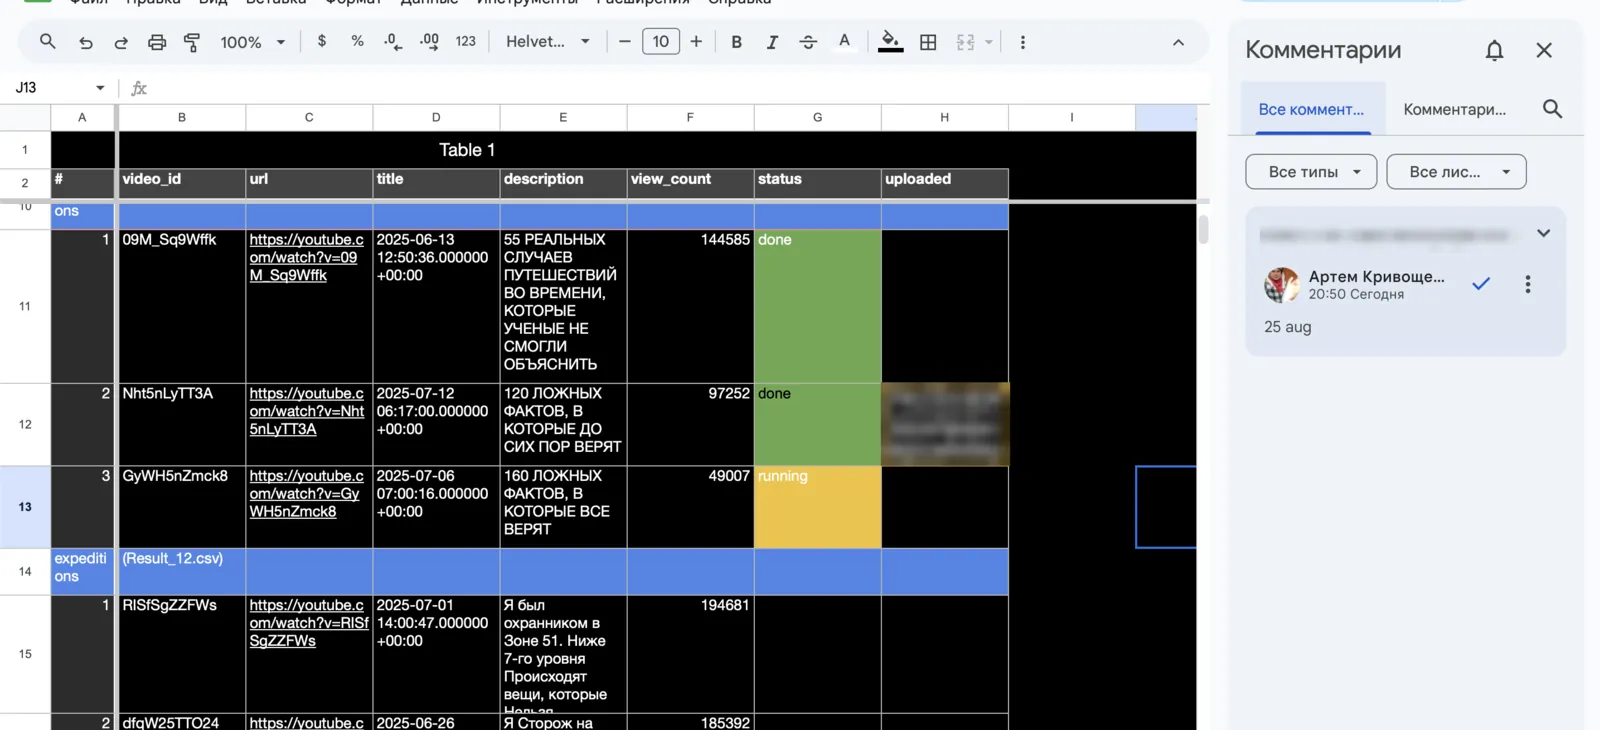
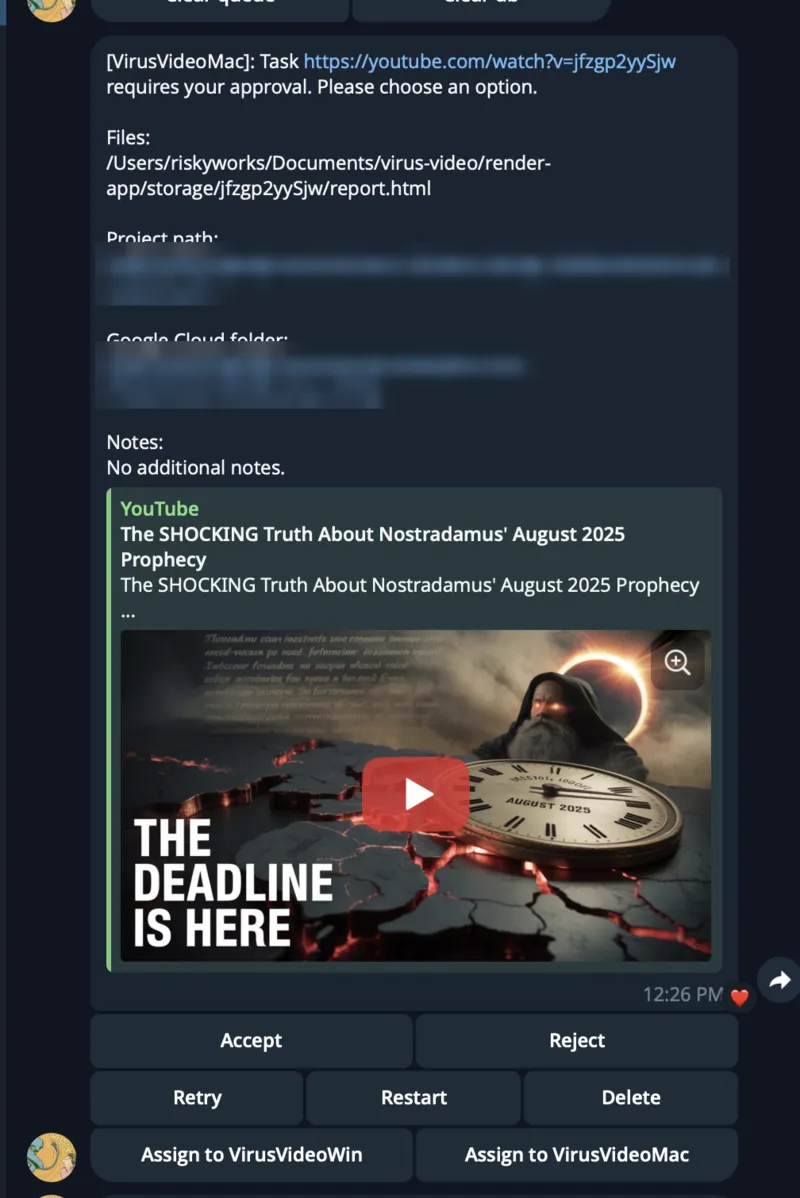
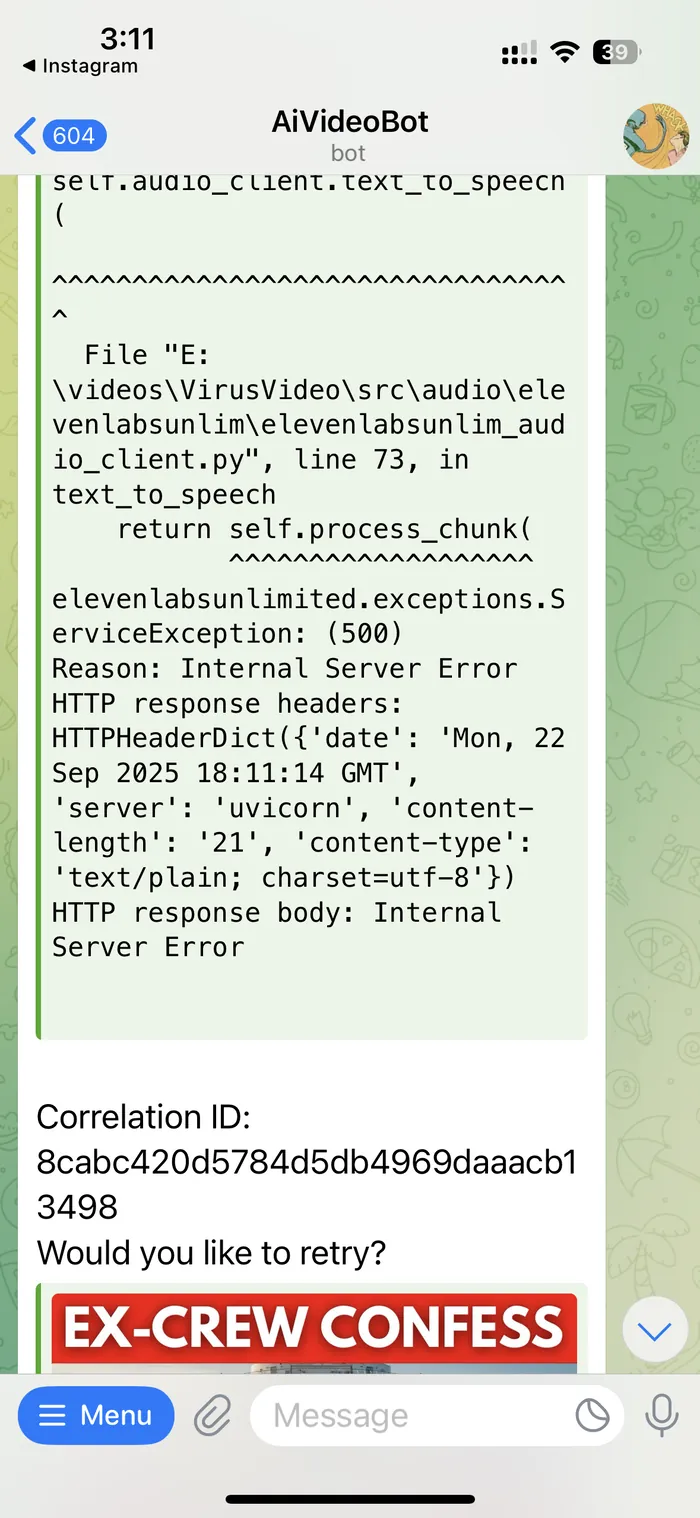
Reference intake, the approval request and an error report with a retry
Operator Guide
For the rest of the team we wrote accompanying documentation, so they could generate videos on the fly as well. The guide covers setting a task in the bot, handling approval requests and errors, and working in the RenderOrc desktop client. In the published copy the cloud folder links and the bot handle are hidden.
Distributed Workers
The worker side of that queue. Several executors connect to one task server, take whatever is next - generate text, transcribe audio, generate images - and run it. At peak five machines on my home network were working at once, a Steam Deck among them, each running a client that pulled tasks from the server and did them.
macOS, Windows and Linux
Development started on macOS, but the client had to run on Windows and Linux as well, and the client stack was picked with that in mind. In the final pipeline the workers were a mix: some machines ran macOS, some Linux, some Windows. The screenshots come from a Windows worker driven over remote desktop from a Mac: first the Python environment and its dependencies get installed, then the worker renders video through Blender and processes the audio track.
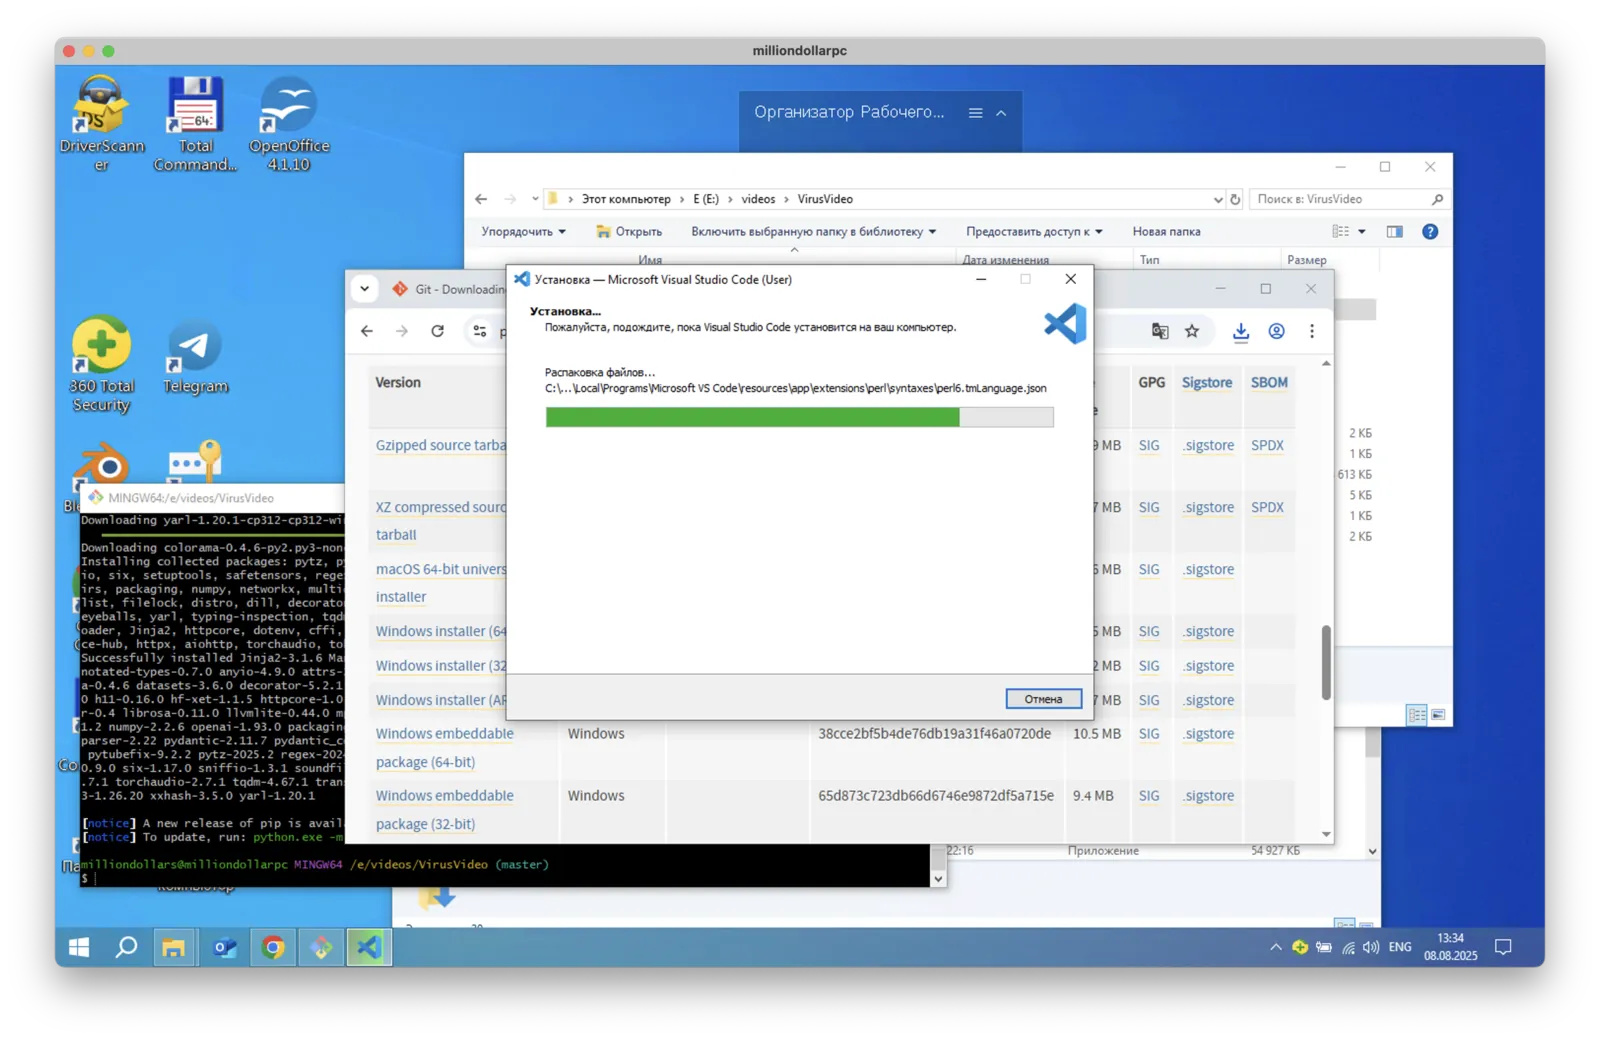
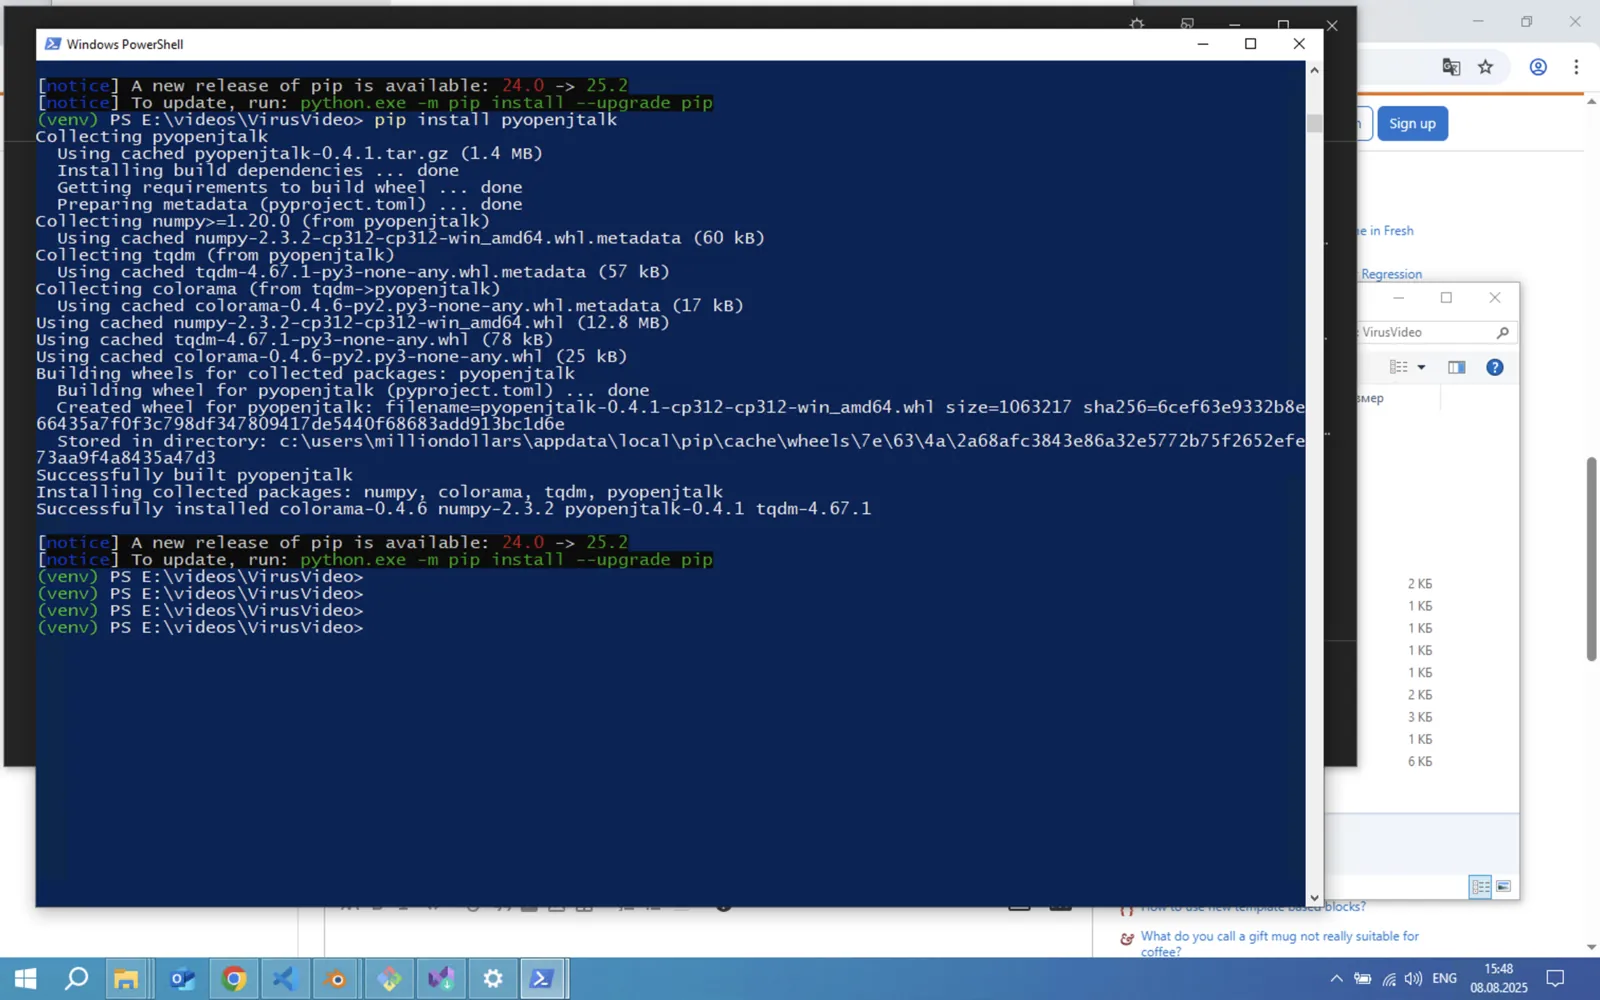
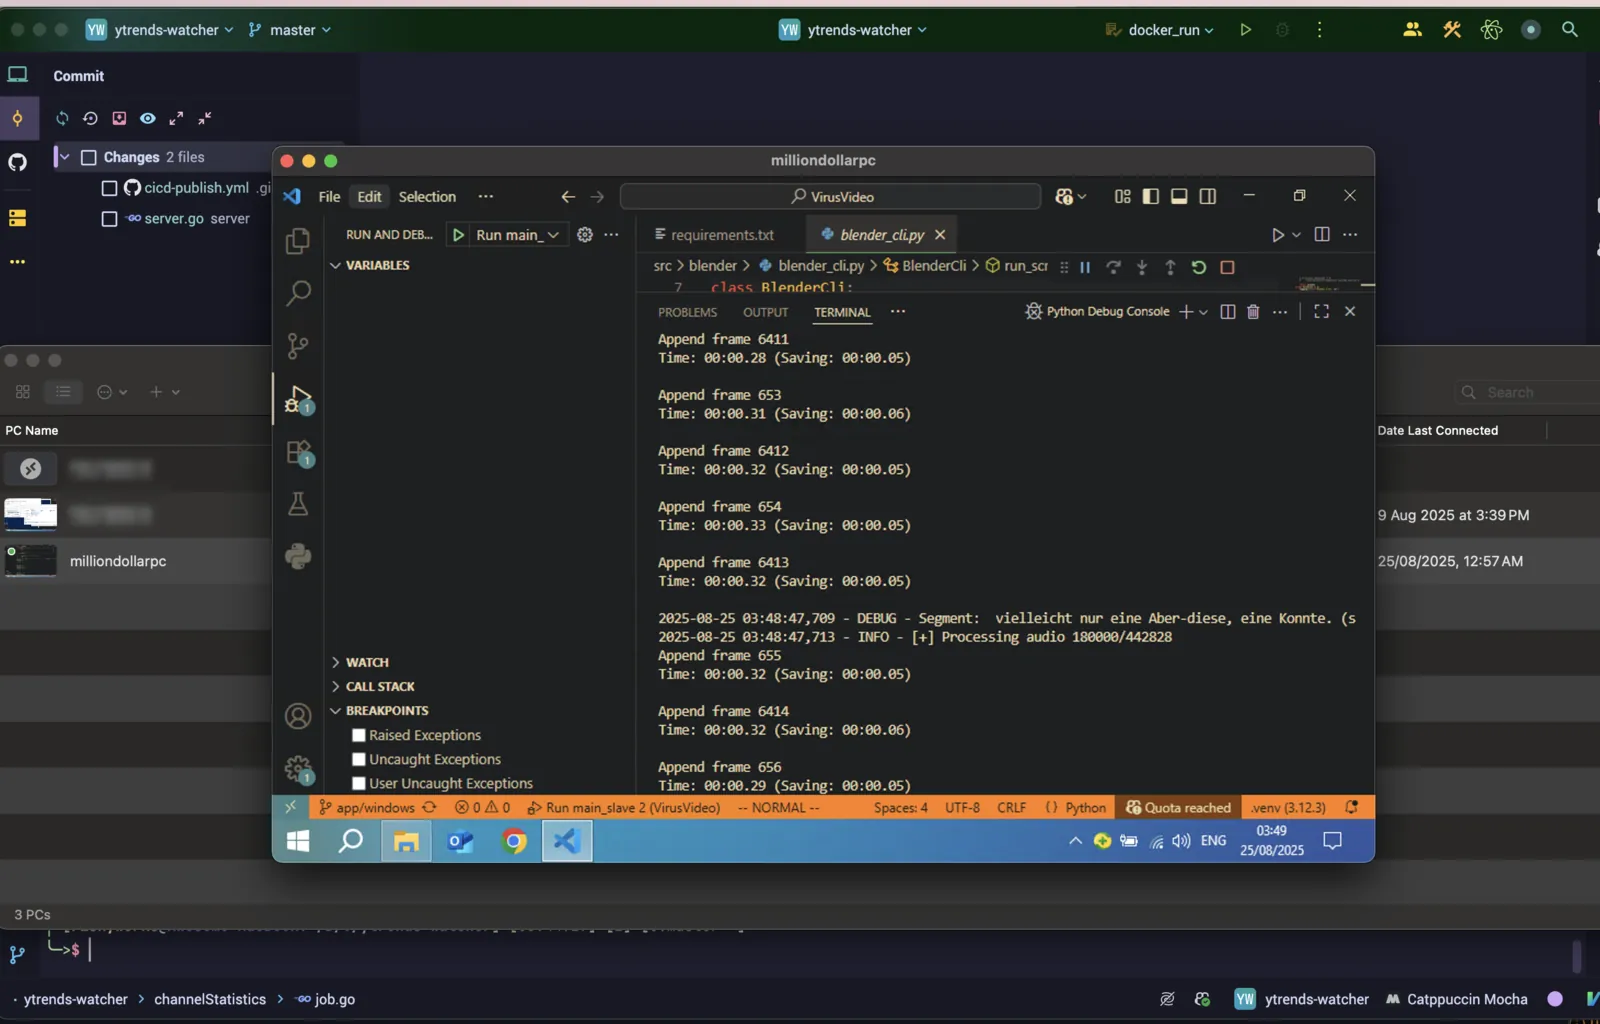
A Windows worker: environment setup, dependencies, Blender render
A Content Forge
In the end there was so much content per day that I had to buy a terabyte of Google Drive to keep the upload queue filled. It was literally a content forge, a conveyor belt, a content factory. The output was a set of videos in several languages and of different lengths, with all the accompanying metadata needed to upload them to YouTube.
Desktop Visual Editor
Fixing a single bad frame through a chat bot is awkward, so the visual side got its own desktop client, RenderOrc. It opens a project, reads it, and lays out every scene image next to the prompt that produced it. A prompt can be rewritten and that scene regenerated on the spot, without rerunning the pipeline or hunting for the frame in a folder.
RenderOrc ran on both Windows and macOS. Besides regenerating an image, it styled it to suit the video: avatars get a drop shadow, content images a shadow and rounded corners, and an image smaller than Full HD is set on a paper-texture background. Every image carries the start and end time of its scene, so it can be checked against the exact moment it covers, in meaning as well as in style. The screenshots follow the client from an early prompt window to the finished app; below them are the splash screen variants generated for it.
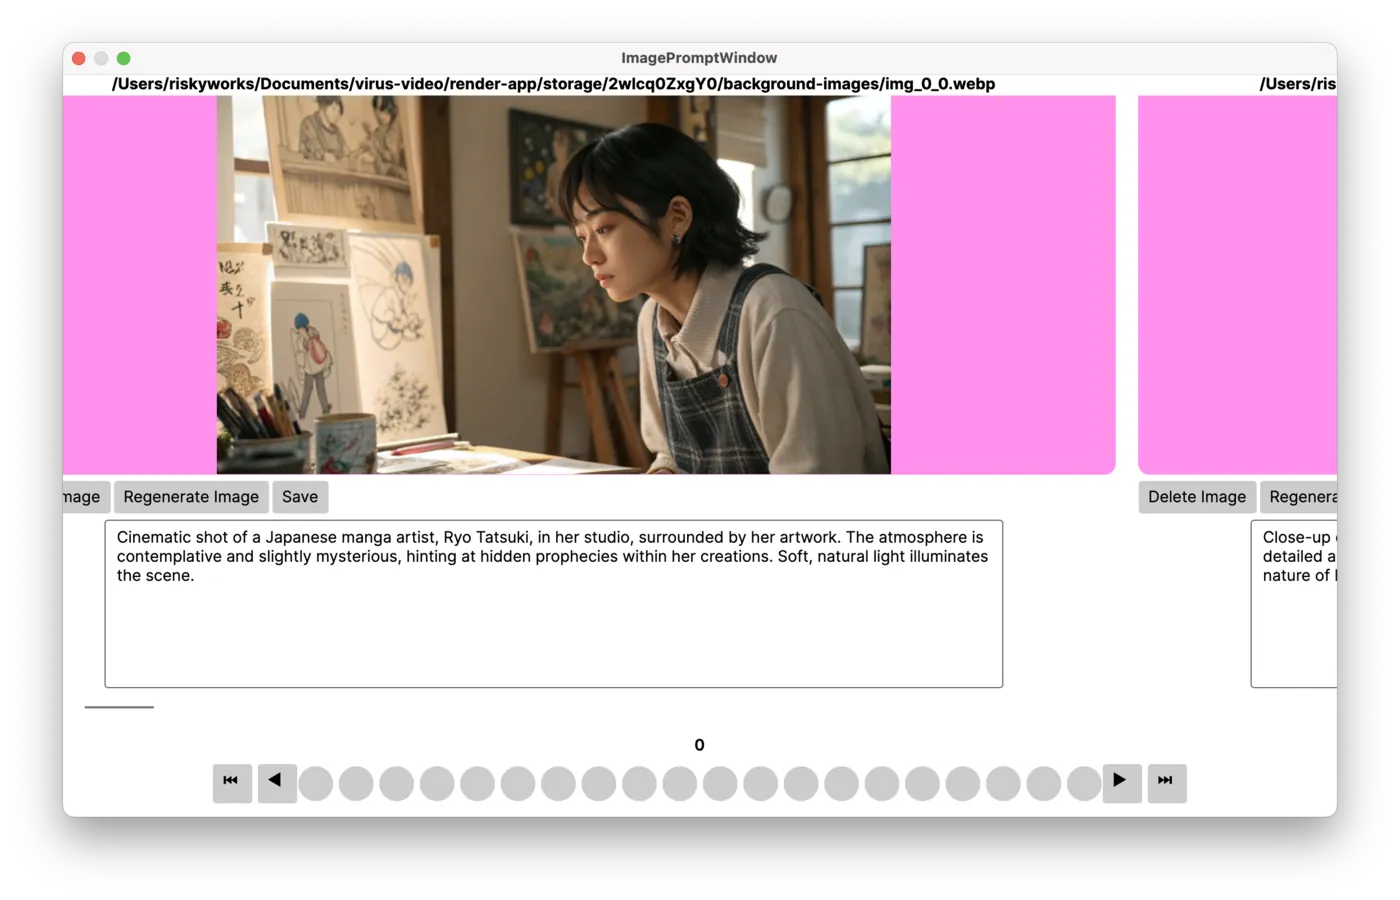
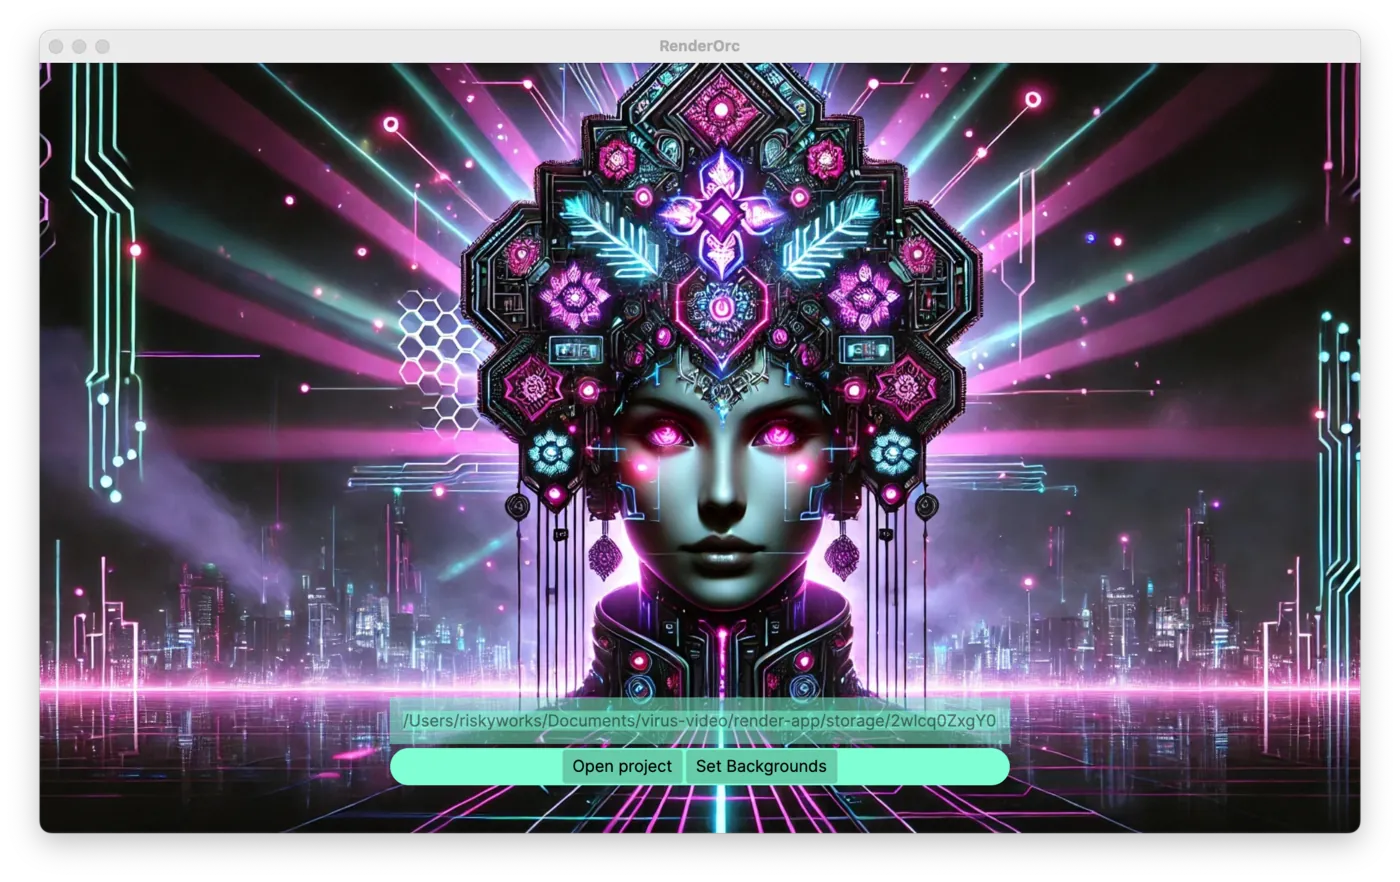
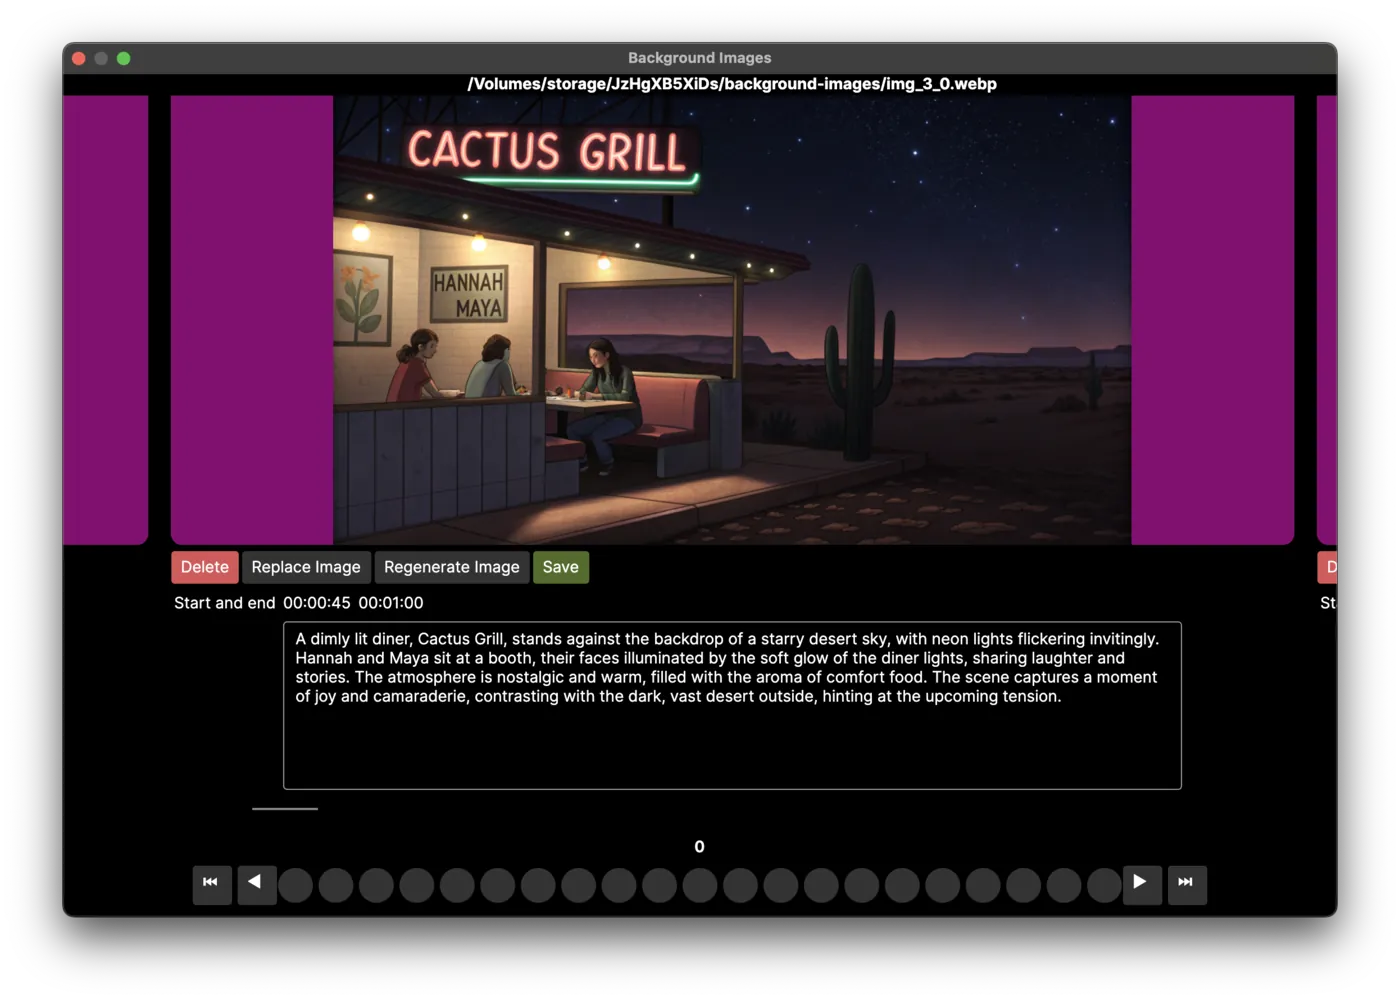
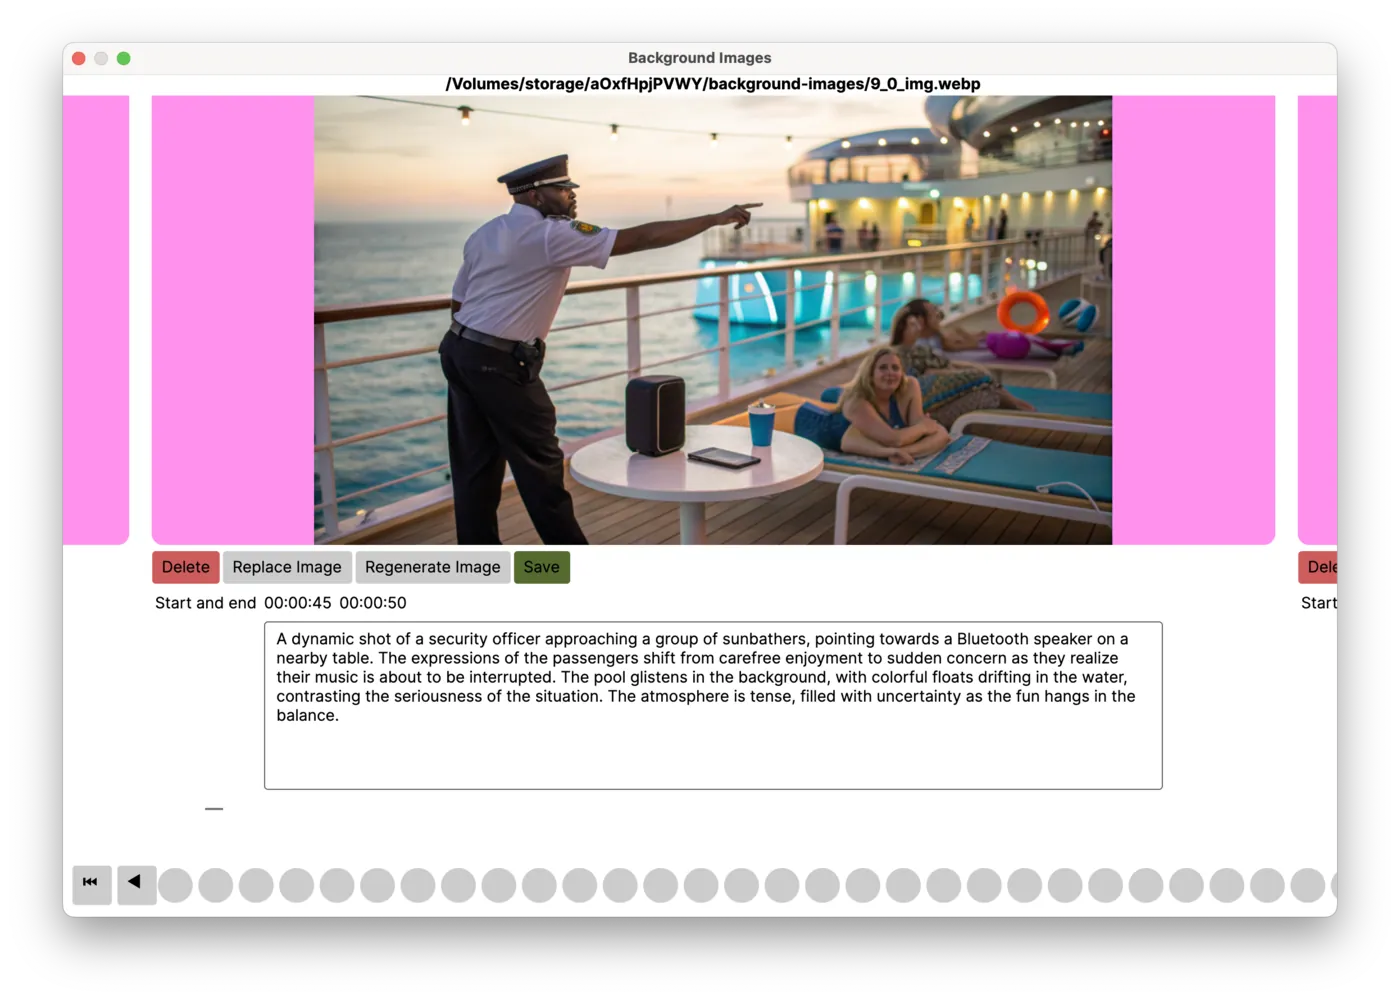
RenderOrc from the first prompt window to the finished editor
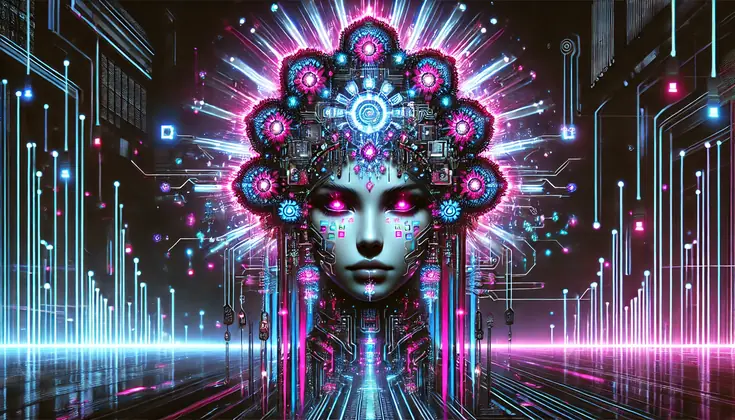
Splash screen variants generated for RenderOrc
Trend Monitoring
Picking what to make next needed data rather than taste, so a separate microservice in Go watches a list of added channels and collects what has taken off there. Those videos become the reference pool the briefs and the cover prompts are built from, which is where the viral patterns described above actually come from.
The watcher itself, running over the tracked channels.
Raising the YouTube API Quota
Monitoring at that scale runs into the YouTube API quota, so we applied to Google for a higher limit on grabbing statistics. The application went through. The project was put on hold not long after, so the raised quota never got to be used at full stretch.
Related
Projects
Traffic Connect, AI Content Orchestration for WordPress Sites
Before: AI article generation had to be run across many WordPress sites, with no single place to control it. After: one admin dashboard queues tasks for every site, and each site picks up its own work through a plugin, built from scratch in about a month.
PREZA, School Presentation Sites with 80,000+ Generated PDFs
Before: school presentation sites needed tens of thousands of ready files that nobody could produce by hand. After: grabbers, parsers and automated multi-threaded generation produced more than 80,000 PDFs, stored in Selectel cold S3 and published on preza.kz and preza.top.
AtomPk Grabber - Product Lists into CSV on Demand
Before: a partner needed the product list off a website collected into CSV again and again, by hand. After: a double-clickable executable that walks the catalogue and writes the CSV, with no Python to install and nothing to configure.
Open for contract collaboration
I am available for contract-based collaboration. If you have an interesting project idea, schedule a call via Calendly.
Schedule a 30-min call